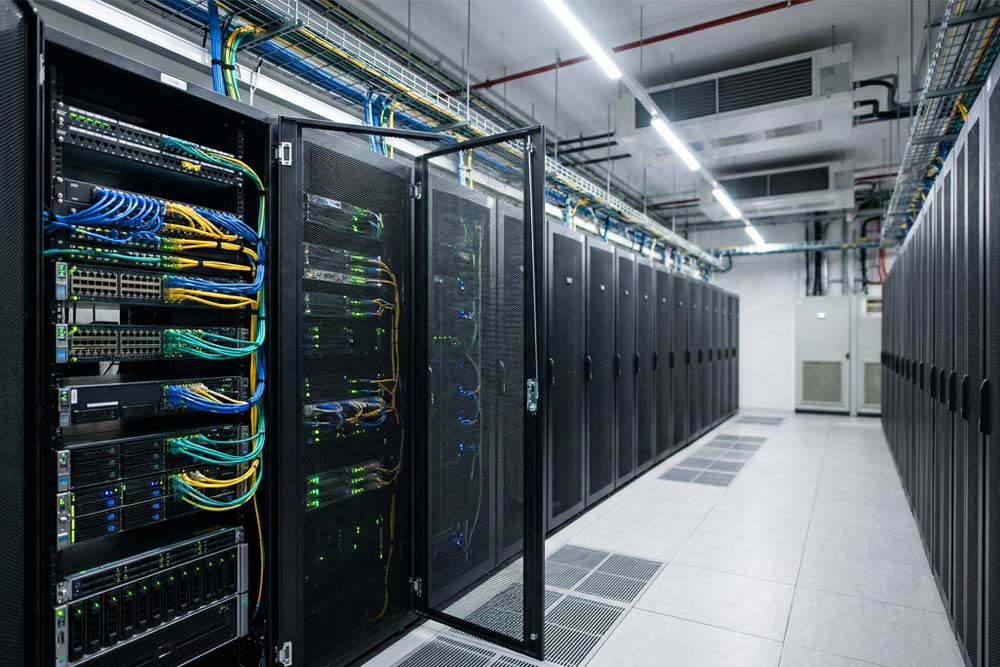
Server clustering refers to a group of servers working together on one system to provide users with higher availability. Clustering reduces downtime and outages: if one server goes down, another takes over automatically.
Here’s how it works. Several servers connect to one shared system.
The moment one server experiences a service outage, the system redistributes the workload to another server. The client never experiences any downtime. Clustered servers generally handle applications with frequently updated data. File, print, database, and messaging servers rank among the most common clusters. Overall, clustering offers a higher level of availability, reliability, and scalability than any single server could provide.
In a clustered server environment, each server owns and manages its own devices. It also keeps a copy of the operating system, plus any applications or services, so it can run the other servers in the cluster. The servers in the cluster work together by design. This protects data and keeps the cluster configuration consistent over time.
Cluster Protection Against Failures and Outages
The primary rationale for server clusters is protection against outages and downtime. As mentioned above, clustered servers offer increased protection against an entire network going black during a power failure. Clustered servers protect against three primary types of outages.
We’ll cover each type of outage in the sections below. In short, server clustering protects against three kinds of failure: software failure, hardware failure, and outages caused by events at the physical server site.
Application / Service Failure
Application and service failures cover any outage caused by critical errors in the software or services that keep a server or data center running. A wide range of factors can cause these failures, and many of them are unavoidable. Most servers implement redundancy measures to prevent this type of failure. Even so, application and service failures are hard to anticipate and prepare for by nature.
Server monitoring data is complex and dense. That makes it hard for admins to pinpoint and resolve issues before they cause an outage. A vigilant, experienced admin can catch many of these issues before they become problems. Still, no admin can fully protect against this type of failure.
System / Hardware Failure
This type of outage occurs as the result of failures with the physical hardware on which the server is running. A wide range of factors can cause these outages, and nearly every component in a server or data center can play a role.
Server components keep improving in reliability and functionality, but none are immune to failure. It can happen from overheating, poor optimization, or a component simply reaching the end of its lifespan. Processors, physical memory, and hard disks are among the components most likely to fail. They’re also some of the most important for keeping a server running.
Site Failure
Events outside the data center environment generally cause site failures. In theory, many kinds of events can cause a site failure. In practice, the most common culprits are natural disasters that cause widespread power outages or damage hardware inside the data center.
Only a careful choice of location can fully offset some natural disaster risks. But businesses can prepare for power outages and related complications with redundancy measures like server clusters. For data centers in areas prone to natural disasters, these redundancy measures matter even more.
Teams can identify and resolve many issues before they lead to one of these three failure types. Even so, redundancy measures like server clustering are the only way to reach near complete reliability. For data centers that need round-the-clock uptime, server clustering is the most reliable way to get there.
The Three Types of Clustering Servers
Server clusters fall into three types, based on how the cluster system (called a node) connects to the device that stores configuration data. The three types are the single (or standard) quorum cluster, the majority node set cluster, and the single node cluster. We cover each one in more detail below.
Single (or Standard) Quorum Cluster
This is the most commonly used cluster type. It comprises multiple nodes with one or more cluster disk arrays that share a single connection device, called a bus. One server manages and owns each of the individual cluster disk arrays within the cluster. The titular quorum refers to the system used to determine whether or not each individual cluster is online and uncompromised.
Single quorum clusters are quite simple in practice. Each node has a “vote”, with which it communicates to the central bus that it is online and functional. As long as more than half the nodes in a single quorum cluster are online, the cluster stays up and running. If more than half the nodes go unresponsive, the cluster stops functioning. It won’t come back online until the team resolves the issues with those nodes.
Majority Node Set Cluster
Like the cluster above, each node in this model owns its own copy of the configuration data. That data stays consistent across every node. This model works best for clusters whose servers sit in different geographic locations.
Majority node set clusters work much like single quorum clusters. The key difference is that they don’t need a shared storage bus, since each node stores its own local copy of the quorum data. While this doesn’t entirely eliminate the utility of a shared bus, it allows for more flexibility when configuring remote servers.
Single Node Cluster
Most often used for testing purposes, this model contains a single node. Teams often use single node clusters as a tool for developing and researching cluster applications. Their lack of failover heavily limits their real-world use, though. Because they contain only one node, a single failure takes down the entire cluster group.
A customer service representative at a local data center or web hosting provider can explain the differences between these three models in more detail. They can also help you decide which one fits your business. Unless your needs are unusual or your servers sit in several locations, the Standard Quorum Cluster is your best bet.
Why Cluster Your Servers?
The key to a protected IT infrastructure lies in redundancy. Clustering servers on a single network gives you the strongest redundancy available. A single error won’t shut down your network, cut off your services, or cost your business revenue. Talk to a customer service representative at a local web hosting provider. They can walk you through the benefits of clustering and help you get started.
Ready to See How Volico Data Center Can Help You?
Got questions? Want to talk specifics? That’s what we’re here for.
Have one of our friendly experts contact you to begin the conversation. Discover how Volico can help you with your Managed Hosting Services needs.
• Call: (305) 735-8098
• Chat with a member of our team to discuss which solution best fits your needs.